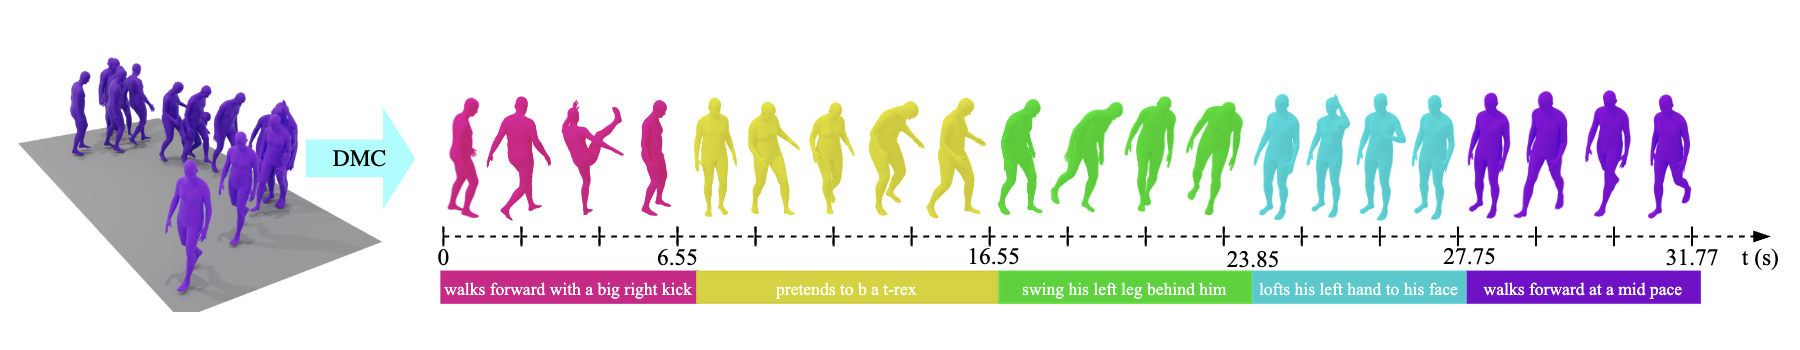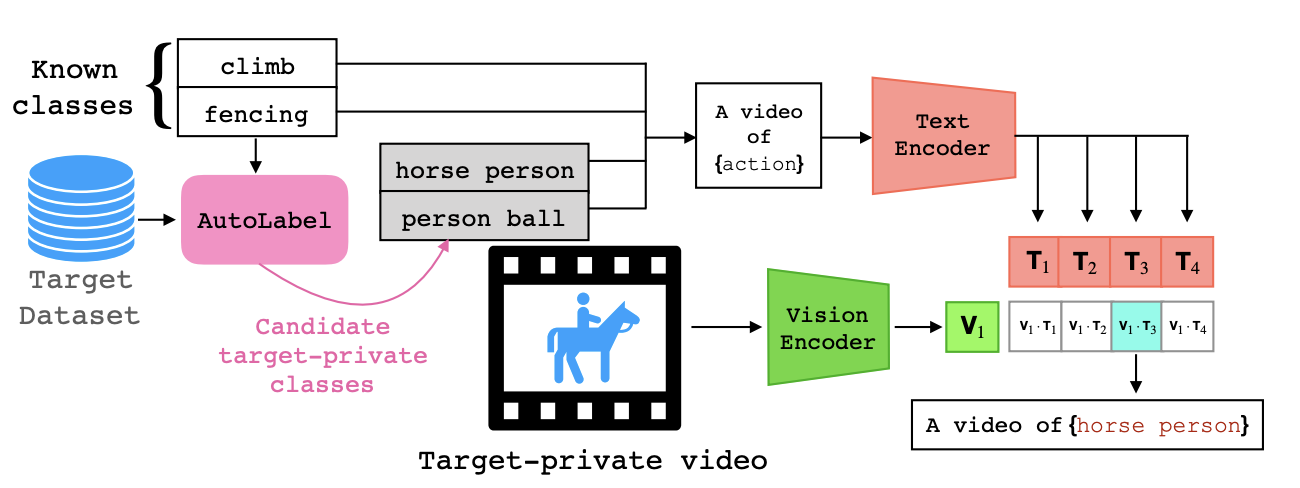
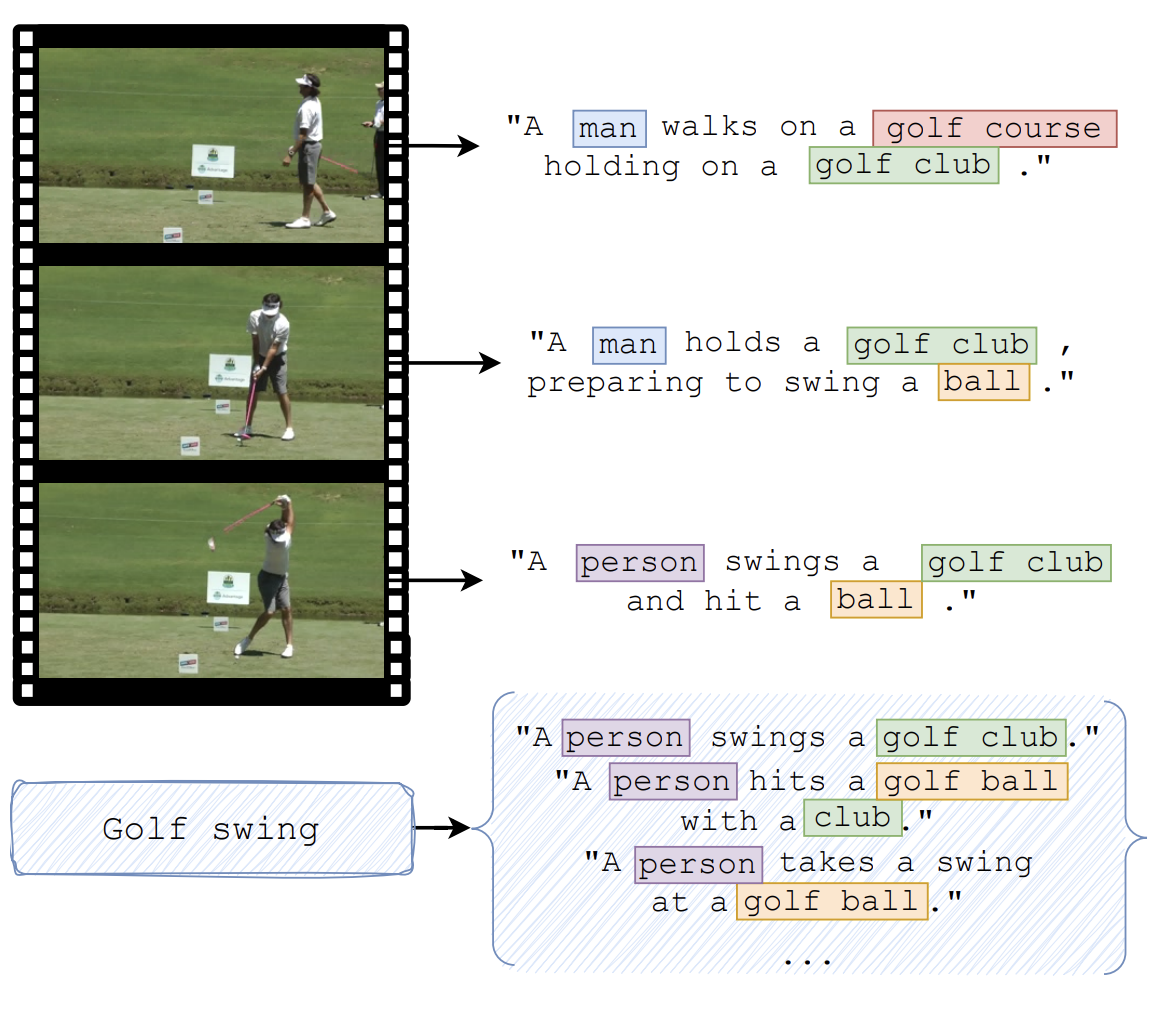
Zero-Shot Temporal Action Localization Through Textual Guidance
Benedetta Liberatori, Alessandro Conti, Lorenzo Vaquero, Paolo Rota, Yiming Wang, Elisa Ricci. Face and Gestures 2026.
Associate Professor @ Department of Psichology and Cognitive Science - University of Trento
Piazza Manifattura 1, edificio 14, - Room 150 - 38068 Rovereto (TN)
Polo Ferrari - Via Sommarive , 9 - Room 110 - (Povo 2) - I-38123 Povo (TN)
Ongoing I am part of the MHUG group of the University of Trento. If you are interested in working or visiting the MHUG group, please fill this form.
I am Paolo Rota, associate professor at the University of Trento and ELLIS member, working in computer vision, machine learning, and multimodal AI. My research focuses on vision-language models and activity recognition, with applications in video analytics and industrial AI.
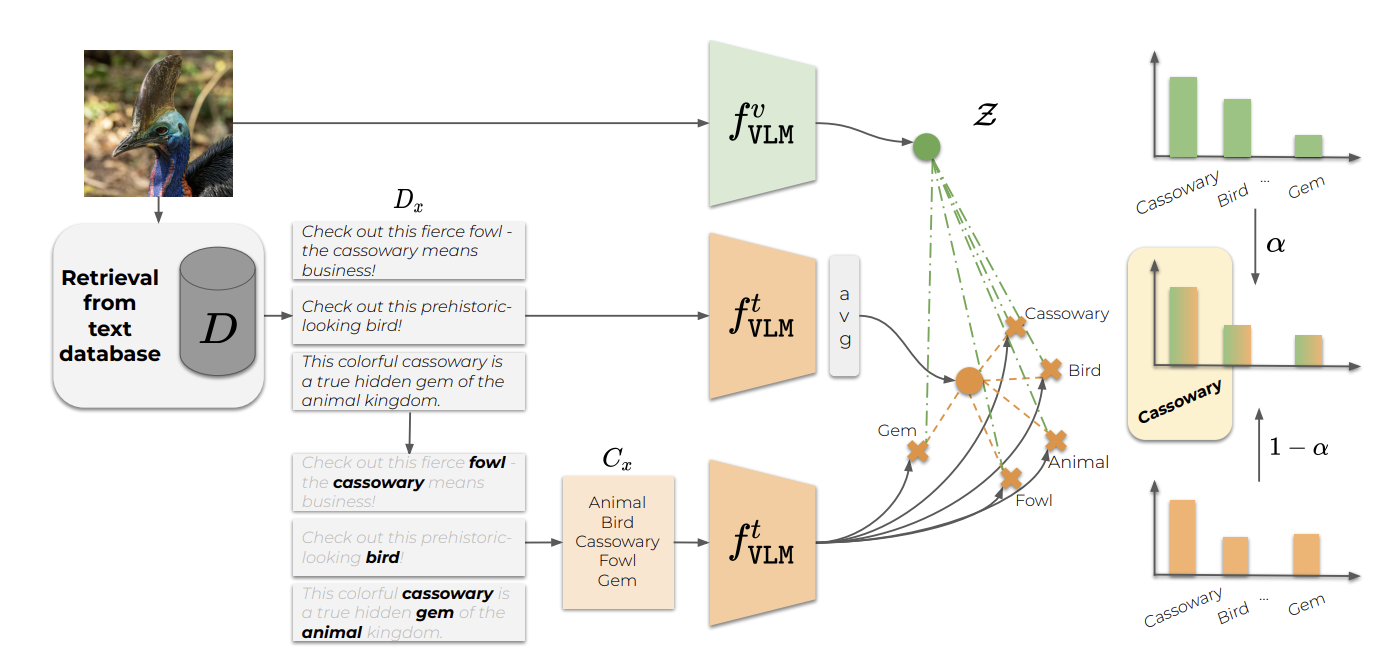
My research focuses on computer vision and machine learning, with a particular emphasis on video understanding and multimodal AI. I investigate methods that bridge vision and language, addressing challenges such as zero-shot action recognition, temporal action localization, and open-world recognition using large vision–language models. More broadly, I work on representation learning and domain adaptation to build systems capable of robust visual understanding in dynamic and real-world environments. I am also interested in evaluation protocols and benchmark design for video analytics, aiming to develop principled and reliable ways to assess multimodal AI systems.
Outside of academia, I co-founded Mountain Maps, a startup that uses AI to enhance outdoor navigation and help people explore mountain environments more safely and enjoyably.
My talk, Foundation Models Beyond Domain Boundaries, closed the week in the session on AI methods, alongside Silvia Storti (University of Verona) and Giulia Lioi (IMT Atlantique). Nice to bring a computer vision and big models perspective to a room of neurophysiologists, and the local programme on open science and TMS-EEG was worth the trip in itself.
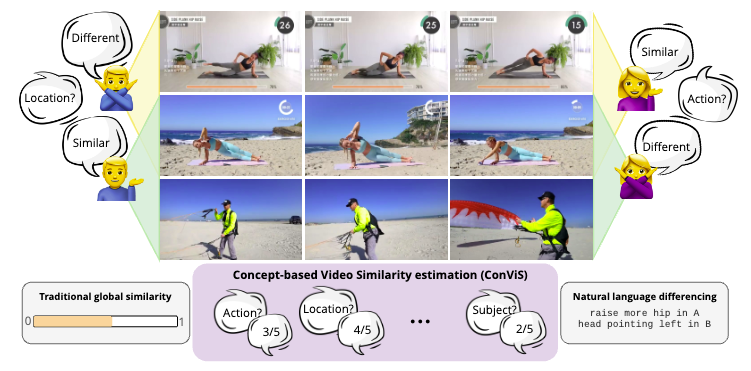
Benedetta's paper Video-Language Entailment for Video Similarity Estimation has been accepted at EMNLP 2026 Findings!
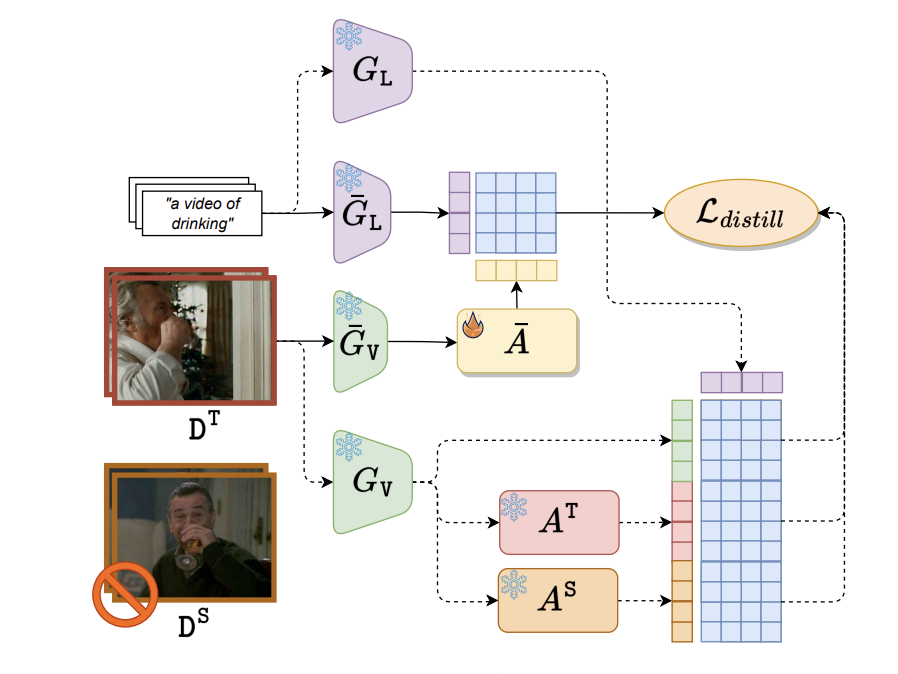
We look at video differencing in the setting models are actually trained for: instead of concatenating two videos to spot what changed, we ask whether the caption of one video is entailed by the other.
The preprint will be on arXiv soon.
Congrats Bene!!